
Introduction: Why This Matters
In my experience, the most revealing moment in modern keyword research comes when you ask a client, “What would your customer actually type into ChatGPT?”
Most pause. Some laugh nervously. Then they say something like, “I don’t know—I guess they’d search the same things they search on Google?”
They wouldn’t. And that gap—between how people search on Google and how they ask AI engines—is where the next wave of organic visibility will be won or lost.
What I’ve found is that traditional keyword research captures a shrinking slice of human intent. People don’t type “best CRM for small business” into ChatGPT. They say: “I run a five-person consulting firm, we’re drowning in spreadsheets, and I need something that won’t take three weeks to set up. What should I look at?” That prompt contains context, constraints, and urgency that no keyword tool can measure. Yet that prompt is exactly what AI engines fan out into sub-queries, retrieve content for, and synthesize into an answer.
This guide exists because prompt-based keyword research is the natural evolution of everything keyword research was trying to do: understand what people want and create content that satisfies it. The difference is that prompts reveal why people want it, how they frame their problem, and what constraints shape their decision. That’s richer than search volume will ever be.
By the end of this guide, you’ll understand how to collect real prompts, map their fan-out patterns, classify their intent, and build content that gets cited in AI answers—not just ranked in traditional search results. Whether you’re a curious beginner opening ChatGPT for the first time or a professional pivoting your strategy, this framework will work for you. For broader context on how AI is reshaping SEO, explore our SEO resource library.
Background / Context: Why Keywords Became Insufficient
Keyword research was built for a search engine that returned ten blue links. You typed a short phrase, Google matched it to indexed pages, and rankings translated into clicks. The entire discipline—volume, difficulty, intent classification—was designed around that model.
That model is fracturing. AI engines don’t match strings. They decompose prompts into sub-queries, retrieve passages, and synthesize answers. The retrieval unit is no longer the page; it’s the paragraph. The matching unit is no longer the keyword; it’s the entity. And the user’s input is no longer a two-word phrase; it’s a conversation .
The data tells a striking story. A study of 25 UK Shopify stores found that measurable search volume fell across all query lengths year-over-year, but the decline was steepest for broad terms (two-word queries down 9.6%) and gentlest for specific terms (five-plus word queries down only 3.0%). The analyst concluded: “The long tail is growing and we simply can’t see it” . Keyword Planner rounds small volumes to zero. Search Console strips low-volume queries for privacy. The conversational prompts that represent real user needs are invisible to traditional tools.
Meanwhile, AI search adoption is accelerating. Consumers are increasingly starting product research inside ChatGPT, Perplexity, and Google AI Mode rather than traditional search . These platforms don’t show a list of links. They show a synthesized answer with citations. If your content isn’t among those citations, you don’t exist for that user—regardless of your Google rankings.
What this means for keyword research: The discipline hasn’t died. It has moved up the stack. You’re no longer researching what strings people type. You’re researching what problems they describe, what language they use, and what sub-queries AI engines generate to answer them. That’s prompt-based research. And it’s the most important keyword skill of 2026.
Key Concepts Defined
Before diving into the framework, let’s establish the language of prompt-based research.
Prompt: A conversational query submitted to an AI engine. Prompts are typically longer than keywords, contain context (who the user is, what they’ve tried, what constraints they face), and often express a problem rather than a search phrase. “How do I get more local customers for my bakery without running discounts?” is a prompt. “bakery marketing” is a keyword .
Prompt-Based Keyword Research: The practice of analyzing real prompts users submit to AI engines, clustering similar prompts by intent, and identifying the sub-queries AI generates to answer them. This reveals content opportunities that traditional keyword tools miss.
Query Fan-Out: The process by which AI engines decompose a single prompt into multiple synthetic sub-queries before retrieving content. When a user asks ChatGPT a question, the system generates two to ten related searches behind the scenes, retrieves passages matching those sub-queries, and synthesizes an answer .
Prompt Cluster: A group of prompts that share the same underlying goal or problem, even if the phrasing varies dramatically. “How to get more bakery customers,” “bakery marketing without ads,” and “why isn’t my bakery showing up on Google Maps” might all belong to the same prompt cluster.
Anchor Query: A representative prompt that defines a cluster. You use anchor queries to map fan-out patterns and audit content coverage .
Node Architecture: Structuring content so every significant section is a self-contained, independently retrievable unit. Each H2 opens with a standalone direct answer (30-60 words) that could be cited on its own, without requiring context from earlier in the article .
Entity: A distinct concept, person, place, or thing that AI systems recognize and reason about. AI engines retrieve based on entity relationships, not keyword strings. Building consistent entity signals across your content is essential for citation .
Citation: A link to a source included in an AI-generated answer. Citations are chosen separately from traditional rankings—a page ranking tenth can be cited while the page ranking first is not .
Atomic Answer: A self-contained response block (40-60 words) placed immediately after a question-phrased heading. Designed for AI extraction and citation.
How It Works: The Step-by-Step Framework
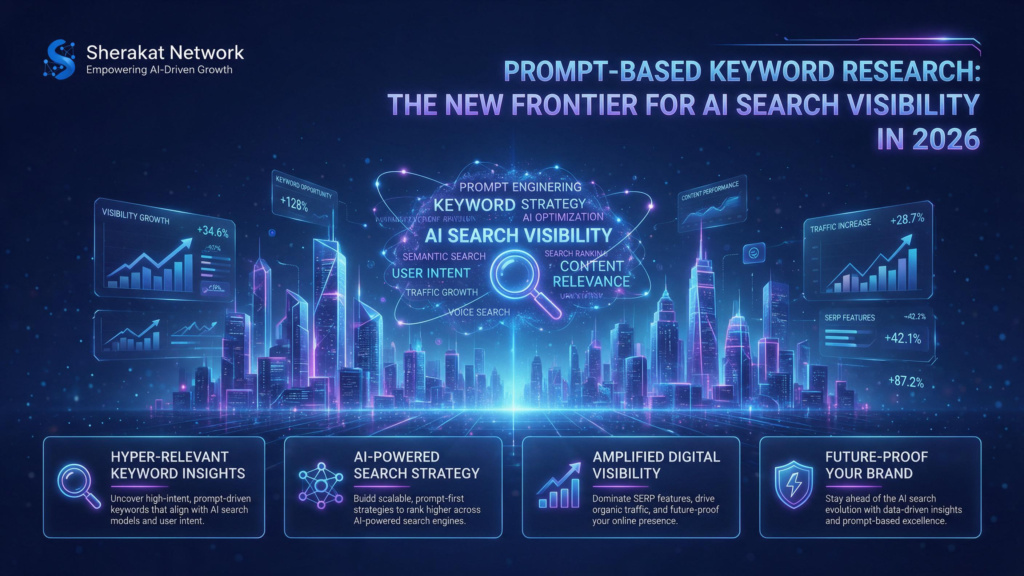
This is the core of the guide. Follow these steps in order, adapting the depth to your available tools and capacity.
Step 1: Collect Real Prompts (Not Keywords)
The foundation of prompt-based research is real language from real users. You need to collect prompts that people actually submit to AI engines—not phrases you invent based on keyword tools.
Method A: Observe AI Autocomplete and Suggestions
Open ChatGPT, Perplexity, or Google AI Mode. Type your seed topic and watch what happens. How does the AI autocomplete your query? What related questions does it suggest? Which phrases appear most often in responses? Patterns like “best way to,” “how can I,” or “should I” reveal how people naturally frame their problems .
Method B: Mine Sales Calls and Support Tickets
Your customers describe their problems in their own words. Sales call transcripts, support tickets, and community forum questions are goldmines of authentic prompt language. A bakery owner might say, “I need more people to find us on Google Maps,” which becomes a prompt you can target.
Method C: Use Prompt Research Tools
Tools like SISTRIX Prompt Research cluster millions of real user prompts into topics, providing estimated AI search volume, intent classification, and customer journey stage. Semrush’s AI Visibility Toolkit shows prompts where competitors appear but you don’t . These tools abstract above individual prompts to reveal the underlying intent space.
Method D: Inverse Prompting
Ask the AI engine what it would search for. Prompt ChatGPT: “What sub-queries would you generate for the question ‘how do I promote my bakery locally?’” The engine will return approximate fan-outs. This is free, fast, and surprisingly revealing .
What you’re building: A list of 20-30 authentic prompts around your core topics. Not hundreds. Twenty is enough to see patterns. Thirty is enough to build a content strategy .
Step 2: Cluster Prompts by Intent
Raw prompts are noisy. They need to be grouped by underlying goal.
Clustering rule: If a user asking Prompt A would be satisfied by the same content that satisfies Prompt B, they belong in the same cluster.
Example cluster for a bakery:
- “How to get more local customers”
- “Bakery marketing without ads”
- “Why isn’t my bakery showing up on Google Maps”
- “Best way to promote a bakery opening”
These four prompts share the same intent: local visibility for a bakery. One comprehensive article could satisfy all of them.
Label each cluster by intent type:
- Informational: The user wants to learn (“how does local SEO work”)
- Comparative: The user is weighing options (“Google Maps vs Yelp for bakeries”)
- Transactional: The user is ready to act (“hire local SEO consultant”)
Intent classification tells you what content format to create. Informational clusters need guides. Comparative clusters need comparison tables. Transactional clusters need service pages .
Step 3: Map the Query Fan-Out for Each Anchor Query
For each prompt cluster, select one anchor query and map what AI engines likely generate as sub-queries.
The seven fan-out dimensions:
For any anchor prompt, map sub-queries across these angles :
- Definition: “what is local SEO”
- Comparison: “Google Maps vs Yelp”
- How-to: “how to set up Google Business Profile”
- Pros/cons: “local SEO benefits for bakeries”
- Examples: “bakery local SEO case study”
- Tools: “best local SEO tools”
- Beginner: “local SEO for beginners”
Manual mapping: Use inverse-prompting to see what the AI generates. Ask ChatGPT: “What sub-queries would you search for to answer ‘how do I get more local bakery customers’?” Record the results.
Tool-assisted mapping: Similarweb’s FAN methodology recommends running a “Fan-Out Coverage Audit” for each anchor query, documenting gaps against your existing content .
What you’re building: A coverage map. For each prompt cluster, which sub-query dimensions do you already cover? Which are gaps? The gaps are your content opportunities.
Step 4: Audit Existing Content for Fan-Out Coverage
Before creating anything new, audit what you already have.
- Pull your top 20 traffic-driving pages.
- For each page, identify which fan-out sub-queries it addresses.
- Check each section: does it open with a standalone direct answer (Node Architecture Rule 1)?
- Are definitions explicit (Rule 2)?
- Do statistics carry full context—number, population, action, timeframe, source (Rule 3)?
What you’ll find: Most existing content covers one or two fan-out dimensions well but neglects the others. A page about “how to promote your bakery” might cover how-to steps but skip definitions, comparisons, and beginner guidance. Those gaps are citation vulnerabilities—AI engines can omit your page from answers on your own topic despite good traditional rankings .
The consolidation opportunity: For most teams, updating existing content to cover missing fan-out dimensions outperforms publishing new articles. You’re building on existing relevance signals rather than starting from zero.
Step 5: Structure Content for Chunk-Level Retrievability
AI engines retrieve passages, not pages. A 3,000-word article is not the unit of retrieval—individual sections are . Your content architecture must reflect this.
Rule 1: Every H2 opens with a standalone direct answer. The first 30-60 words of every section must answer that section’s question completely, as if it’s the only content a reader (or an AI) will see. No “as I discussed above.” No pronoun references to previous sections.
Rule 2: Definitions are always explicit. “Query fan-out is the process by which an AI engine transforms a user’s prompt into multiple retrieval sub-queries,” not “query fan-out, which most SEOs have heard about by now.” AI engines match explicit definitions. Implied definitions are invisible .
Rule 3: Statistics carry full context. Every quantified claim needs a number, a population, an action, a timeframe, and a source. “27% of fan-out sub-queries remain consistent across different searches of the same query” is citation-eligible. “Fan-out is inconsistent” is not .
Additional formatting:
- Use question-phrased headings (“What Is Query Fan-Out?” not “Overview of Query Fan-Out”)
- Keep paragraphs to two to four sentences
- Include comparison tables and structured data where relevant
- Place Atomic Answers at the start of sections
Step 6: Build Entity Consistency Across Your Content
AI engines understand brands through entities, not keywords. The words, entities, and phrases that appear alongside your brand shape what the model thinks you are and when it should recommend you .
Entity consistency checklist:
- Organization schema: Complete, with logo, founder, and sameAs links to authoritative profiles
- Person schema for authors: Verifiable affiliations, prior works, and credentials
- Consistent brand descriptions: The same core language about what you do across your site, social profiles, and external mentions
- Topical associations: Content that connects your brand to the concepts you want to be known for
Why this matters for prompt research: When AI engines fan out a prompt, they retrieve based on entity relationships. If your brand isn’t clearly associated with the entities in the prompt, you won’t be retrieved—regardless of keyword optimization. Entity consistency is the foundation of citation eligibility .
Step 7: Track Citations, Not Just Rankings
Rankings alone no longer predict traffic. You need to track whether your content appears in AI answers.
Manual tracking: Search your anchor queries in Google, ChatGPT, and Perplexity. Look for your domain among the citations. Record which pages are cited and in what position.
Tool-assisted tracking: Tools like Profound, Otterly, Peec, and SE Ranking AI Search track citation appearances across AI platforms. Treat these like rank trackers in 2010: imperfect, worth running, but don’t over-trust the absolute numbers .
Google Search Console’s generative AI report: Rolled out worldwide in August 2026, this shows AI Overview and AI Mode impressions by page. Limitation: no query dimension, no click data, no citation position.
What to track weekly:
- Which anchor queries cite your domain
- Which pages are cited
- Citation position (first source vs. last)
- Competitor citation share for the same queries
Step 8: Prioritize by Citation Probability, Not Volume
Not all prompts have equal citation potential. Prioritize based on:
| Signal | High Priority | Low Priority |
|---|---|---|
| Prompt length | 15+ words, contextual | 3-5 words, generic |
| Intent | Comparative, transactional | Broad informational |
| AI Overview presence | Absent or weak | Strong, comprehensive |
| Competition | Forum posts, thin content | Major brands, definitive guides |
| Entity clarity | Clear relationships | Ambiguous topics |
The single biggest mistake: Adding prompt research on top of existing keyword work without consolidating. Most content backlogs are keyword-aligned but entity-thin and fan-out-incomplete. A consolidation pass beats new production .
Step 9: Iterate Weekly, Not Monthly
AI citations drift faster than traditional rankings. One analysis found neighboring citations rotate at approximately 70% per week, and only 1.4% of news articles remain cited permanently . You need to monitor more frequently than you did for Google rankings.
Weekly cadence:
- Run your top 10 anchor queries through Google, ChatGPT, and Perplexity
- Document citation changes
- Note new prompts appearing in AI autocomplete
- Update content that has lost citations
The iteration mindset: AI search visibility is inherently volatile. Your strategy should assume drift, not permanence. Consistent monitoring and rapid response matter more than perfect initial optimization.
Why It’s Important
Prompt-based keyword research isn’t an academic exercise. It’s the difference between being visible in the channels where users are increasingly starting their research and being invisible.
The traffic reality. Consumers are shifting discovery to AI platforms. Shopify reported AI-referred sessions to its merchants up 197% year-over-year . If your content isn’t citation-eligible, you’re not part of that traffic.
The measurement gap. GA4 misreports AI search traffic because referrer information is stripped by many AI engines. You cannot optimize what you cannot see. Prompt research provides a leading indicator—citation appearances—that doesn’t depend on referrer data .
The competitive opportunity. Most brands are still doing keyword research and ignoring prompts. The ones who build prompt-based content strategies now will establish citation authority before the competition catches on. That head start compounds.
What happens if you ignore this: You optimize for keywords that trigger AI summaries. You rank position one and watch clicks flatline. You present traffic projections that never materialize. The tools said the keywords were good. The keywords weren’t the problem. The problem was measuring the wrong thing. For more on how this fits into broader SEO strategy, see our complete online business guide.
Sustainability in the Future
Prompt-based research is evolving fast. Here’s what to watch.
Citation volatility is structural. Drift rates of 54-59% per week show no sign of stabilizing. This is a characteristic of AI platforms, not a transitional phase. Your strategy should assume constant change and build monitoring into your workflow .
Platform-specific optimization matters. ChatGPT favors comparison and how-to content. Google AIO prefers structured lists and definitions. Perplexity rewards data-rich tables and explicit citation density. A page that excels on one platform is not guaranteed to excel on another.
Entity consistency will become table stakes. As AI engines refine their entity graphs, brands with inconsistent descriptions across the web will be systematically disadvantaged. Investing in entity clarity now pays compound returns later .
The sustainable approach: Build prompt clusters, not keyword lists. Optimize for chunk-level retrievability, not page-level rankings. Track citations, not just positions. And accept that AI search visibility is inherently volatile—your strategy should assume drift, not permanence. For resources on building sustainable systems, explore our resources section.
Common Misconceptions
Misconception 1: “Prompt research replaces keyword research.” No. It extends it. Volume-based keyword research remains useful for branded, transactional, and local queries where volume still predicts traffic. Prompt research addresses the informational and comparative queries that AI engines now summarize.
Misconception 2: “If I rank position one, I’ll be cited in AI answers.” Not necessarily. Research found that only 12% of URLs cited by ChatGPT, Perplexity, and Copilot rank in Google’s top 10. Rank is the entry fee. Citation is a separate selection process .
Misconception 3: “Schema markup guarantees citations.” Schema makes you legible. Entity coverage determines citation. Controlled experiments found schema additions alone produced changes indistinguishable from noise .
Misconception 4: “I can use the same content structure for keywords and prompts.” Prompt-optimized content requires Node Architecture: standalone direct answers at the start of every section, explicit definitions, and statistics with full context. Traditional SEO content often fails these tests .
Misconception 5: “Longer content performs better in AI search.” Length doesn’t matter. Chunk-level retrievability does. A well-structured 1,200-word article beats a rambling 3,000-word article for citation eligibility.
Misconception 6: “I should target every prompt I find.” No. Prioritize by citation probability, intent match, and your ability to create genuinely better content. A prompt list is a menu, not a mandate.
Misconception 7: “Prompt research is a one-time project.” AI citations drift faster than rankings. You need weekly monitoring and iteration, not a quarterly review.
Recent Developments
Three developments in 2025-2026 have reshaped prompt-based research.
1. Google Search Console launched generative AI performance reports. Rolled out worldwide in August 2026, these show AI Overview and AI Mode impressions by page. For the first time, you can measure AI-driven visibility natively in GSC—though without query or click data.
2. Prompt research tools matured. SISTRIX Prompt Research clusters 62 million prompts into 1.4 million topics. Semrush AI Visibility Toolkit shows competitor prompt gaps. Similarweb published the FAN methodology for GEO keyword research. What was manual and speculative a year ago is now tool-assisted and systematic .
3. Query fan-out became a recognized discipline. The concept that AI engines decompose prompts into sub-queries before retrieval is now central to GEO and AEO strategy. Tools like queryfanout.ai and Otterly simulate fan-out. Similarweb’s FAN methodology provides a complete workflow for mapping and auditing .
Success Stories
Case Study: The Bakery’s Prompt Discovery
A local bakery was struggling to compete for “bakery [city]” keywords against established directories. Prompt research revealed a different opportunity: people were asking AI engines questions like “how do I find a bakery that does custom cakes for birthdays,” “best bakery for gluten-free options near me,” and “bakery that delivers early morning.”
These prompts were specific, conversational, and poorly served by existing content. The bakery created dedicated pages for each use case—custom cakes, gluten-free, early delivery—with standalone answers at the top of each section. Within three months, they were being cited in AI answers for eight different prompt queries, driving calls from customers who found them while researching their specific need.
The key insight: The bakery couldn’t win the generic keyword. It could win the specific prompt.
Case Study: The SaaS Company’s Fan-Out Audit
A project management SaaS analyzed its content against fan-out patterns for its core topic: managing remote teams. They found that their pillar page covered “time zone coordination” and “async communication” but missed “remote meeting fatigue,” “tracking productivity without surveillance,” and “onboarding remote employees.”
They expanded the pillar page to cover the missing dimensions, opening each section with a standalone answer. Within two months, AI citation frequency for the page increased 40% across tracked prompts.
The key insight: Consolidation beat new production. The gaps were in existing content, not missing pages. For more on this approach, see our competitor keyword research guide.
Case Study: The Freelance Writer’s Entity Fix
A freelance writer’s portfolio was ranking well but never cited in AI answers. The problem: no Person schema, inconsistent brand descriptions across profiles, and no clear entity associations.
After deploying complete Person schema with sameAs links, standardizing the bio across all platforms, and connecting content to recognizable industry entities, citation frequency increased within weeks—without any content changes.
The key insight: Entity signals are the bridge between ranking and citation. Without them, AI can’t verify authorship or authority .
Real-Life Examples
Example 1: The Plumber’s Prompt Gap
A plumbing company analyzed prompts and found people were asking AI engines: “how do I know if I need a new water heater,” “why is my water pressure low in the shower only,” and “how much should a plumber charge to fix a leak.” The company created content answering these specific questions with standalone answers at the top of each section. They were cited in AI answers for seven of ten tracked prompts within eight weeks—driving calls from people who found them while researching their issue.
Example 2: The B2B Marketer’s Comparison Opportunity
A B2B software company found that AI engines were answering comparative prompts like “Asana vs Monday for small teams” with generic summaries. They created a detailed comparison page with a structured table, explicit criteria, and standalone answers for each comparison dimension. The page became the most-cited source for that prompt cluster within three months—not because the company had higher authority, but because the content was more chunk-retrievable.
Example 3: The E-commerce Store’s Use-Case Prompts
An online store selling ergonomic chairs analyzed prompts and found: “best office chair for tall person,” “chair for small home office,” and “ergonomic chair under $200.” These weren’t keywords they’d targeted. They were prompts people asked AI engines. The store created dedicated landing pages for each use case, with product recommendations and standalone answers. Product page traffic from AI referrals increased 60% within two months.
These examples connect to broader patterns in how information systems evolve. The global supply chain adapted to complexity through modularization and real-time data. Content strategy is evolving the same way—through chunk-level optimization and entity clarity. Even the mental health field has seen how frameworks must adapt to changing conditions.
Conclusion and Key Takeaways
Prompt-based keyword research isn’t a replacement for traditional keyword research. It’s the next layer—the one that addresses how AI engines actually retrieve, synthesize, and cite content.
Key Takeaways:
- Prompts reveal context, constraints, and urgency that keywords cannot
- AI engines fan out every prompt into sub-queries; citations go to pages matching those sub-queries
- The retrieval unit is the passage, not the page—structure content for chunk-level retrievability
- Node Architecture rules: standalone answers, explicit definitions, statistics with full context
- Entity consistency is the foundation of citation eligibility
- Only 12% of URLs cited by AI engines rank in Google’s top 10—rank is the entry fee, not the scorecard
- Track citations weekly; AI visibility drifts faster than traditional rankings
- Consolidate existing content for fan-out coverage before publishing new articles
- The biggest mistake is adding prompt work without restructuring content for AI retrieval
Your next step: Collect ten prompts your audience asks AI engines. Map the fan-out for each. Audit your existing content for coverage. Fill the gaps with standalone answers. Then check whether your content appears in AI answers—not just search results. For more strategic context, explore our complete online business guide and our full SEO resource library.
FAQs
Q1: What is prompt-based keyword research?
A: Analyzing real conversational queries users submit to AI engines, clustering them by intent, and mapping the sub-queries AI generates to answer them. It reveals opportunities that traditional keyword tools miss .
Q2: How is a prompt different from a keyword?
A: Prompts contain context (who the user is, what they’ve tried, constraints) and often express a problem rather than a search phrase. “How do I get more bakery customers without ads?” is a prompt. “bakery marketing” is a keyword .
Q3: Do I still need traditional keyword research?
A: Yes, for branded, transactional, and local queries where volume still predicts traffic. Prompt research addresses informational and comparative queries that AI engines now summarize.
Q4: What is query fan-out?
A: The process by which AI engines decompose a prompt into multiple synthetic sub-queries before retrieving content. Citations go to pages matching the sub-queries, not the original prompt .
Q5: How do I see what sub-queries AI generates?
A: Use inverse-prompting (ask the AI what it would search for), tools like queryfanout.ai, or Similarweb’s FAN methodology .
Q6: What is Node Architecture?
A: Structuring content so every significant section is a self-contained, independently retrievable unit. Each H2 opens with a standalone direct answer .
Q7: Why do AI engines retrieve passages instead of pages?
A: The retrieval unit is the passage because AI systems match sub-queries to specific content chunks. A 3,000-word article is not the unit of retrieval—individual sections are .
Q8: What is an Atomic Answer?
A: A self-contained 40-60 word response block placed immediately after a question-phrased heading. Designed for AI extraction and citation.
Q9: How do I collect real prompts?
A: Observe AI autocomplete, mine sales calls and support tickets, use prompt research tools, and inverse-prompt the AI engines .
Q10: How many prompts do I need to start?
A: Twenty to thirty authentic prompts around your core topics are enough to see patterns and build a content strategy .
Q11: What is a prompt cluster?
A: A group of prompts that share the same underlying goal or problem, even if the phrasing varies. One comprehensive article can target an entire cluster.
Q12: How do I map fan-out for an anchor query?
A: Use inverse-prompting or tool-assisted mapping across seven dimensions: definition, comparison, how-to, pros/cons, examples, tools, and beginner guidance .
Q13: What is a fan-out coverage audit?
A: Checking your existing content against the fan-out dimensions for each anchor query to identify gaps. Most content covers one or two dimensions well but neglects the others .
Q14: Why should I audit existing content before creating new content?
A: Consolidation beats new production. Most content backlogs are keyword-aligned but fan-out-incomplete. Filling gaps in existing pages builds on existing relevance signals .
Q15: How do I structure content for AI citation?
A: Use question-phrased headings, standalone answers at the start of every section, explicit definitions, statistics with full context, and short paragraphs .
Q16: What is entity consistency and why does it matter?
A: AI engines understand brands through entities, not keywords. Consistent brand descriptions, complete schema, and clear topical associations make you eligible for retrieval .
Q17: How do I track AI citations?
A: Manual spot-checking, Google Search Console’s generative AI report, or tools like Profound, Otterly, and SE Ranking AI Search .
Q18: What is Google Search Console’s generative AI report?
A: A report showing AI Overview and AI Mode impressions by page, country, device, and date. It has no query dimension and no click data.
Q19: Why don’t rankings predict AI citations?
A: Only 12% of URLs cited by AI engines rank in Google’s top 10. Citation is a separate selection process based on chunk-level retrievability and entity clarity .
Q20: How often should I monitor AI citations?
A: Weekly for priority prompts. AI citations drift faster than traditional rankings—neighboring citations rotate at approximately 70% per week .
Q21: What’s the biggest mistake in prompt-based research?
A: Adding prompt work without restructuring content for AI retrieval. Node Architecture and entity consistency are prerequisites, not optional extras.
Q22: Should I optimize for ChatGPT, Google AIO, and Perplexity differently?
A: Yes. ChatGPT favors comparison and how-to content. Google AIO prefers structured lists and definitions. Perplexity rewards data-rich tables and citation density.
Q23: Does schema markup guarantee AI citations?
A: No. Schema makes you legible. Entity coverage determines citation. Controlled experiments found schema additions alone produced changes indistinguishable from noise .
Q24: What is the difference between GEO and AEO?
A: GEO (Generative Engine Optimization) is broader, covering visibility across all generative AI platforms. AEO (Answer Engine Optimization) focuses specifically on being cited in AI-generated answers.
Q25: Can I do prompt research for free?
A: Yes. AI autocomplete observation, inverse-prompting, and manual fan-out mapping are free. Google Search Console’s generative AI report is free. Paid tools add efficiency, not access.
Q26: How do I find prompts competitors miss?
A: Use Semrush AI Visibility Toolkit’s competitor prompt analysis or manually test anchor queries in AI engines to see who gets cited .
Q27: What is citation drift?
A: The rapid turnover of sources cited in AI answers. Neighboring citations rotate at approximately 70% per week, and only 1.4% of news articles remain cited permanently .
Q28: How long does it take to see AI citation results?
A: Citation patterns drift quickly—some shifts appear within weeks. But sustained visibility requires consistent entity signals, fan-out coverage, and content freshness.
Q29: What is the FAN methodology?
A: A GEO keyword research workflow from Similarweb: Find anchor queries, Audit fan-out coverage, and Navigate gaps with traditional keyword validation .
Q30: What’s the one thing I should do differently after reading this guide?
A: Collect ten prompts your audience asks AI engines. Map the fan-out. Audit your existing content. Fill one gap with a standalone answer. Then check if your content appears in AI answers. For more guidance, explore our SEO category.
About Author
[Sana Ullah Khan Kakar, Content and Article Writing Specialist]
This guide was written based on hands-on experience adapting keyword research strategies for AI search across multiple industries since 2024, including local services, B2B SaaS, and content publishing. The frameworks outlined here have been tested against Google AI Overviews, ChatGPT, and Perplexity citation data.
Free Resources
Prompt-Based Keyword Research Tools:
- queryfanout.ai — real fan-out queries from Google API
- SISTRIX Prompt Research — prompt clustering and AI search volume
- Semrush AI Visibility Toolkit — competitor prompt gaps
- Similarweb FAN methodology — GEO keyword research workflow
- Google Search Console — generative AI report
Recommended Reading on Sherakat Network:
- Start Online Business 2026 Complete Guide
- The Alchemy of Alliance: A Comprehensive Guide to Building a Successful Business Partnership
- SEO Category
- Resources Category
- Blog Category
External Resources:
- The Daily Explainer: Mental Health Complete Guide
- The Daily Explainer: Global Supply Chain Management Guide
- World Class Blogs: AI and Machine Learning
- World Class Blogs: Remote Work and Productivity
- World Class Blogs: Climate Policy Agreements
- World Class Blogs: Culture and Society
Discussion
What’s your experience with prompt-based keyword research? Have you found prompts that revealed opportunities your keyword tools missed? Share your insights in the comments below.
If you found this guide helpful, consider sharing it with someone who’s trying to adapt their keyword strategy for AI search. The shift is real—but the professionals who adapt will thrive.
Have questions? Reach out via our contact page.